
Forecasting and decision analytics
Forecasts that planners actually use, because the system explains itself, shows its uncertainty and records the reasons for overrides.
Hierarchical forecastingConfidence made visible
ViewAI & Machine Learning
Applied machine learning and language-model systems built with the evaluation, guardrails and monitoring that separate a working capability from an impressive demonstration.
Overview
We start every engagement by assessing whether the use case is worth building at all, and say so plainly when it is not. What we do build ships with evaluation suites, fallback paths and cost monitoring as release gates.
Typical engagement
Starts with: a short, fixed-scope discovery
First release: in production early, not at the end
Team: named in the proposal
Exit: documented and rehearsed from day one
Capabilities
A structured review of where models genuinely beat rules or people, with cost, risk and data readiness scored per use case.
Retrieval-augmented assistants, document processing and agentic workflows built on hosted or self-hosted models.
Forecasting, churn, propensity and anomaly detection integrated into the systems where decisions are actually made.
Inspection, classification and document extraction pipelines for field, factory and back-office environments.
Feature stores, training pipelines, model registries, deployment and drift monitoring.
Model documentation, bias assessment, human-review design and records aligned to emerging regulatory expectation.
How we deliver
Step 01
We rank candidate use cases on value, feasibility and data readiness, and name the ones that are not worth building yet.
Step 02
A time-boxed build against your real data with success criteria agreed in advance and a genuine option to stop.
Step 03
Evaluation suites, guardrails, fallbacks, cost controls and human review paths before general release.
Step 04
Drift detection, quality sampling and a retraining cadence tied to measured degradation rather than the calendar.
Technology
We keep a deliberately narrow toolset so the depth is real. Within it, the choice is made per engagement based on your team and your constraints rather than our preferences.
Where your team already knows a technology well, that usually outweighs a marginal technical advantage elsewhere — and we will say so.
| Area | Tools and platforms |
|---|---|
| Models | Claude, GPT, Llama, Mistral, fine-tuned open weights |
| Frameworks | PyTorch, scikit-learn, LangChain, LlamaIndex, Hugging Face |
| Platforms | AWS Bedrock, Azure AI, Vertex AI, OCI Generative AI, Databricks |
| Serving & monitoring | FastAPI, Triton, MLflow, Evidently |
Where this applies
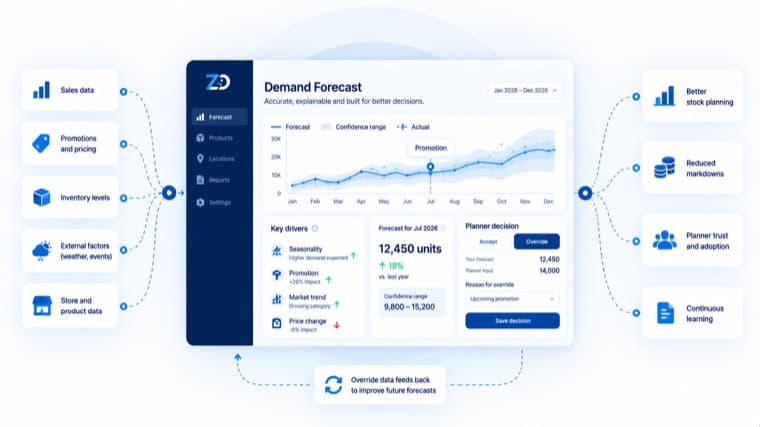
Forecasts that planners actually use, because the system explains itself, shows its uncertainty and records the reasons for overrides.
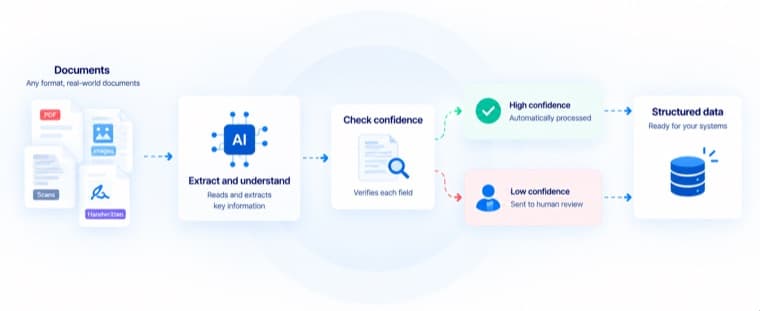
Extracting structured data from messy real-world documents, with confidence thresholds tuned to the cost of being wrong and people kept on judgement.
Questions
The questions clients actually ask about this practice, including the awkward ones.
Almost every client says this and it is usually partly true. The assessment phase tells you honestly whether the data supports the use case, what remediation is needed, and whether a narrower problem would deliver value sooner.
Not unless you direct it. We deploy through enterprise endpoints with training opt-out and zero-retention terms, or self-host open-weight models inside your environment where policy requires it.
You constrain and you measure: retrieval grounded in your own sources, structured output validation, refusal paths for low confidence, and an evaluation suite run on every change. The human review step is designed in, not treated as a fallback.
A short fixed-scope build on your real data against success criteria agreed in advance. You keep the code, the evaluation harness and the findings whether or not the work proceeds.
Related practices
Most work combines two or three practices under a single delivery lead.
Corporate sites, portals and web applications.
Explore service02Drupal builds, modules, migrations and support.
Explore service03Native and cross-platform apps for iOS and Android.
Explore service04Custom platforms, integrations and product engineering.
Explore service05Research, product design and design systems.
Explore service06Migration, cloud-native architecture and cost control.
Explore serviceStart a conversation
An hour with our team, no charge and no obligation. You will leave with a point of view on the problem whether or not you work with us.
Monday to Saturday, 10:00 – 19:00 IST